KIP Student Eligibility Prediction
PROJECT OVERVIEW & OPERATIONAL CONTEXT
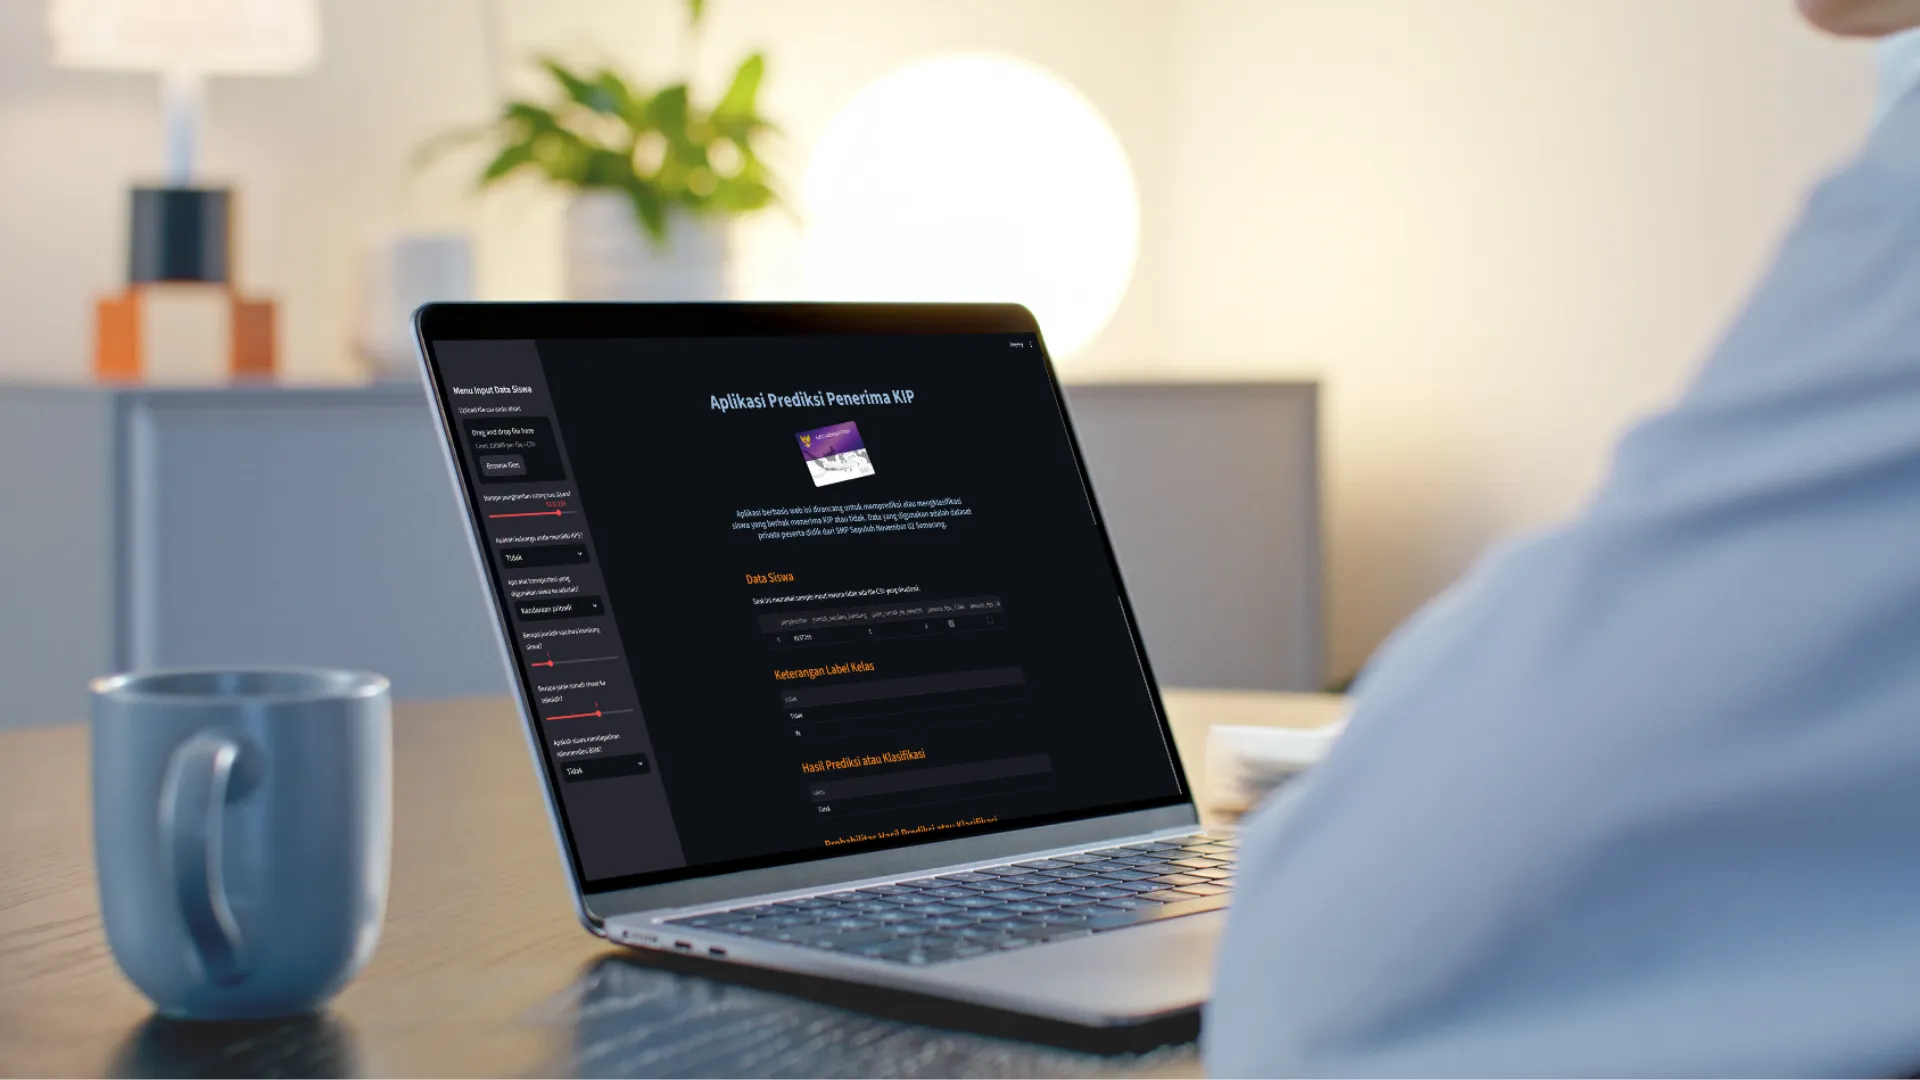
KIP Student Eligibility Prediction is an applied machine learning decision-support system engineered to automate the evaluation of candidate eligibility for the Program Indonesia Pintar (PIP) scholarship program across junior high schools. Manually evaluating hundreds of student administrative records from national Dapodik registries is labor-intensive and prone to administrative inconsistency. This system resolves the bottleneck by implementing an end-to-end classification pipeline trained on historical student records from SMP Sepuluh Nopember 02 Semarang. Continuous indicators (parental income, sibling count, commute distance) and categorical indicators (KPS card enrollment, transportation mode, BSM aid recommendation) are transformed into a 10-dimensional feature space and modeled using a Gaussian Naive Bayes (GaussianNB) classifier. Serialized into a compact binary artifact and served through an interactive Streamlit web dashboard, the architecture supports both real-time manual parameter tweaking and batch CSV ingestion, providing transparent posterior class probabilities to aid institutional committees in allocating educational assistance fairly.
PROBLEM STATEMENT & SYSTEM CONSTRAINTS
Disparate feature scales between unnormalized monthly parental income ($10^6$ IDR with variance ~10^11) and binary indicators created extreme numerical variance imbalance in Gaussian likelihood calculations, while an 81.6% negative class skew naturally biased MAP decision boundaries toward rejection. Furthermore, single-candidate web queries risked feature-space misalignment when generating categorical dummy variables without reference schema concatenation.
- Automate the classification of prospective junior high school students into KIP scholarship recipients ('Ya') and non-recipients ('Tidak').
- Standardize candidate evaluation by modeling six essential socioeconomic and demographic attributes derived from institutional Dapodik school records.
- Mitigate training-serving feature drift by implementing dynamic reference-schema concatenation for categorical one-hot encoding during live inference.
- Compute calibrated posterior class probabilities (P(Eligible | X) vs. P(Ineligible | X)) to support administrative review of borderline applicants.
- Deliver an accessible, zero-dependency browser-based interface via Streamlit supporting both interactive manual input and batch CSV uploads.
Dynamic Schema Dummy Alignment
Concatenates incoming user query DataFrames with reference training data prior to pd.get_dummies to guarantee exact 10-dimensional vector alignment during single-sample inference.
Gaussian Naive Bayes Classifier
Calculates maximum a posteriori class predictions using class prior probabilities and continuous Gaussian feature likelihood densities across all 10 feature coordinates.
Dual-Class Posterior Probability Engine
Computes continuous posterior probability distributions for both eligible and ineligible classes, giving evaluators granular certainty metrics beyond hard binary thresholds.
Multi-Input Administrative Dashboard
Delivers an intuitive Streamlit interface featuring sliders for continuous attributes (income, siblings, distance) and select boxes for discrete welfare markers.
Batch CSV Ingestion Module
Integrates an automated CSV file uploader in the sidebar to rapidly parse, validate, and evaluate external student cohorts against the fitted model.
Decoupled Artifact Serialization
Encapsulates the fitted GaussianNB model into a standalone pickle artifact, cleanly separating the Jupyter exploratory training pipeline from web serving.
Pandas reference-aligned dummy encoding + 10-dimensional feature vector assembly + Gaussian Naive Bayes (GaussianNB) probabilistic classifier + Pickle model serialization + Streamlit web serving dashboard
Student Profile Ingestion & Validation
Ingest student attributes via interactive Streamlit sidebar widgets or uploaded tabular CSV files and assemble raw feature series.
Reference Concatenation & Dummy Encoding
Concatenate the query record with the headless reference dataset to perform consistent one-hot expansion across KPS, transport, and BSM fields.
10-Dimensional Feature Matrix Assembly
Slice the first row of the dummy-expanded DataFrame to isolate the 10-dimensional aligned feature vector matching modelNBC_kip.pkl training schema.
Gaussian Likelihood & Prior Computation
Pass the 10-dimensional vector through GaussianNB to calculate log-likelihoods across continuous Gaussian feature densities weighted by empirical class priors.
Posterior Probability & Label Assignment
Normalize class log-probabilities into posterior confidence scores and determine the predicted class label via maximum a posteriori (MAP) argmax.
Streamlit Reactive Dashboard Rendering
Render encoded feature tables, predicted status ('Ya' / 'Tidak'), and exact posterior probability distributions directly to the browser UI.
SYSTEM EVALUATION & EMPIRICAL VALIDATION
VERIFIED_TELEMETRYThe Gaussian Naive Bayes classifier was evaluated on the complete 500-student historical dataset from SMP Sepuluh Nopember 02 Semarang across 10 encoded feature dimensions. Under the standard maximum a posteriori decision rule with empirical priors (0.816 for non-recipients and 0.184 for recipients), the model achieved an overall accuracy of 81.60% across 408 true negative classifications, reflecting a highly conservative baseline driven by prior odds and wide continuous income variances. Analysis of posterior probabilities revealed that prospective candidates with active KPS welfare cards, low parental earnings, and BSM recommendations exhibited significantly elevated eligibility likelihoods ranging from 20.6% to 27.6% (compared to baseline priors of 18.4%), providing administrative review committees with actionable continuous risk scores. On standard workstation CPU hardware, end-to-end inference—spanning reference DataFrame concatenation, categorical dummy expansion, and GaussianNB forward pass—executed in under 3.2ms per query, ensuring frictionless real-time responsiveness within the Streamlit web dashboard.
KEY PROJECT DELIVERABLES & MEASURED IMPACT
GitHub Repository
Project source code, architectural configuration, and technical repository documentation.
Technical Documentation & Spec
Primary architectural specification: PRO-16 // AI-03 (Python, scikit-learn, Pandas, NumPy).
Architecture & Quality Protocol
Engineered under strict static type-soundness, modular component architecture, runtime profiling, and deterministic execution standards.
BPBD Kebumen Website Replication
Responsive government web portal replication built with React 18, React-Bootstrap, and Bootstrap 5, featuring modular news feeds, interactive operational carousels, responsive municipal telemetry tables, dynamic search widgets, and structured emergency dispatch channels for regional disaster mitigation transparency.
Jakarta Hotel Review Sentiment Analysis
End-to-end natural language processing pipeline mining Google Maps reviews via SerpAPI, normalizing text with negation-preserving NLTK lemmatization, and deploying a maximum-margin Linear Support Vector Classifier through an interactive Streamlit web dashboard for real-time guest sentiment inference.